The bench
Electricity per million tokens, card by card
exhibit ninety-eight The bench
Published 2026-10-30 (UTC)
A small (human) team and a fleet of AI agents.
What a million tokens of writing costs in electricity on each graphics card this site has measured, at one national price, computed only from board watts and writing speeds already published on earlier pages: on the same two models, from about three and a half cents on a laptop card to fifty-eight cents on a pair of used NVIDIA GeForce RTX 3080 (10 GB) cards. Board power only, one caller at a time, idling counted separately, and the arithmetic shown once so a reader can redo it at their own rate.
ask about this page → assistant.strata2signal.com · in beta, still being tested
hardware on this page: RTX PRO 6000 Blackwell (96 GB) · RTX 3090 (24 GB) · RTX 5090 Laptop GPU (24 GB) · RTX 3080 (10 GB) · RTX 3090 Ti (24 GB) · RTX 3080 Ti (12 GB) · RTX 5080 (16 GB) · the mini PC · the pair — two RTX 3080s in one 2021 desktop → research.strata2signal.com/hardware/ · the roster is in beta, still being tested
the short version
A token is a piece of a word: in this site's own prose, about four-fifths of a word by the count on [How the speed tool works](/how-the-speed-tool-works/) (343 words came to 415 to 420 tokens), so a million tokens is roughly 800,000 words of answers. Writing a million of them with the mixture-of-experts model this workshop runs (it uses about 4 billion of its 26 billion parameters for each token) cost 3.42 cents of board electricity on an NVIDIA GeForce RTX 5090 Laptop GPU (24 GB) held to 95 W, 8.39 to 9.74 cents on an NVIDIA GeForce RTX 3090 Ti (24 GB) and 8.94 to 9.32 cents on an NVIDIA GeForce RTX 3090 (24 GB) depending on the power cap, a limit set on what a card may draw, and 12.87 to 15.23 cents on two used NVIDIA GeForce RTX 3080 (10 GB) cards sharing the model. With a dense 24-billion-parameter model, one that uses every parameter for every token, every figure is three to five times higher: 15.93 cents on the laptop card, 57.91 on the pair. The price is 18.31 cents a kilowatt-hour, the U.S. residential average for July 2026, the rate this site's running-costs page uses. Nothing was measured for this page; every figure is a published one put through one formula. Board power, not the wall; one caller; and idling is its own bill, printed separately: a 3090 Ti holding a model and doing nothing costs about $30 a year, and the box that answers around the clock here about $17 a month at the meter.
3,491 words, about 16 minutes to read.
The summary is this page’s own; what was dropped, and why, is in this page’s receipt file.
What is being counted, and at what price
A language model writes in tokens, pieces of words. When a graphics card writes them it draws power, and the card's own driver reports that draw once or twice a second. The benches behind this page multiply each run's mean board watts by the seconds the runtime spent writing, divide by the tokens written, and print joules per thousand tokens. A joule is one watt for one second; 3,600,000 joules are one kilowatt-hour, the unit on an electricity bill. From a published joule figure to money is one line of arithmetic, and this page is that line applied to every card this site has a published joule figure for.
The price is 18.31 cents a kilowatt-hour, the average price of electricity to an American home in July 2026 as the U.S. Energy Information Administration publishes it (Electric Power Monthly, table 5.6.A, the edition released 2026-09-24), the rate What it costs to run a high-end AI rig at home uses. Three of the pages this one draws from print the June 2026 figure, 18.34 cents, and The cost of intelligence prices its owned answers at June's rate; the two months are 0.16 per cent apart. The agency's newest reading as this page went up is 18.16 cents for August 2026 (the edition released 2026-10-23), 0.8 per cent below July's; this page keeps July's so its cents sit beside the running-costs page's, and every cent here is 0.8 per cent lower at the newer rate. None of these is our bill, and none is yours.
The arithmetic, once
Take a 3090 at its own 350 W limit, writing the mixture model: a mean board draw of 240.49 W at 136.618 tokens a second, its page's medians. 240.49 divided by 136.618 is 1.76 joules a token; the page's own figure, from the runtime's decode clock, is 1,758.13 joules per thousand tokens. A million tokens is a thousand times that: 1,758,130 joules, which is 1,758,130 ÷ 3,600,000 = 0.4884 kilowatt-hours, which at 18.31 cents is 8.94 cents. Every cell in the table is that: joules per thousand tokens × 1,000 ÷ 3,600,000 × 18.31. To use your own rate, replace the 18.31.
The table
Every row ran the same frozen prompt on the same runtime version: ollama 0.32.13, Q4_K_M weights, an 8-bit cache, 256 tokens out, the median of three scored runs, board power read from the driver at 2 Hz. The mixture model is gemma4:26b, 26 billion parameters of which about 4 billion work on each token, at a 131,072-token window on every row. The dense model is mistral-small3.2:24b, 24 billion parameters all working, at 65,536 tokens on the single cards, the largest each held whole under the runtime's own placement, and 49,152 on the pair, with every layer forced onto the cards. The desktop cards were read in one computer on 2026-09-17 and 2026-09-18; the laptop part on 2026-09-21 and 2026-09-22, in its own chassis, on its own driver, by the same harness. The letter after each row is the page it came from.
| Card and power setting | Model | Tokens a second | Board W, mean | J per 1,000 tokens | Cents per million tokens | Page |
|---|---|---|---|---|---|---|
| RTX 5090 Laptop GPU, 95 W, fixed | Mixture | 118.424 | 79.64 | 672.50 | 3.42 | (a) |
| RTX 5090 Laptop GPU, Dynamic Boost, 140–150 W | Mixture | 155.251 | 122.57 | 787.76 | 4.01 | (a) |
| A 3090, 250 W | Mixture | 125.6 | 230 | 1,832 | 9.32 | (c) |
| A 3090, 300 W | Mixture | 136.139 | 241.53 | 1,771.71 | 9.01 | (b) |
| A 3090, 350 W, its own limit | Mixture | 136.618 | 240.49 | 1,758.13 | 8.94 | (b) |
| A 3090 Ti, 300 W | Mixture | 145.908 | 240.58 | 1,648.85 | 8.39 | (b) |
| A 3090 Ti, 350 W, flagged by its page | Mixture | 147.823 | 282.64 | 1,909.96 | 9.71 | (b) |
| A 3090 Ti, 450 W, its own limit | Mixture | 147.560 | 283.01 | 1,915.13 | 9.74 | (b) |
| Two 3080s, 250 W each | Mixture | 114.8 | 290 | 2,531 | 12.87 | (c) |
| Two 3080s, 300 W each | Mixture | 115.4 | 346 | 2,994 | 15.23 | (c) |
| RTX 5090 Laptop GPU, 95 W, fixed | Dense | 28.839 | 90.31 | 3,131.56 | 15.93 | (a) |
| RTX 5090 Laptop GPU, Dynamic Boost, 140–150 W | Dense | 44.897 | 135.76 | 3,019.40 | 15.36 | (a) |
| A 3090, 250 W | Dense | 33.3 | 235 | 7,076 | 35.99 | (c) |
| A 3090, 300 W | Dense | 47.838 | 289.86 | 6,059.20 | 30.82 | (b) |
| A 3090, 350 W, its own limit | Dense | 46.880 | 273.35 | 5,842.92 | 29.72 | (b) |
| A 3090 Ti, 300 W | Dense | 42.969 | 296.64 | 6,902.38 | 35.11 | (b) |
| A 3090 Ti, 350 W | Dense | 53.354 | 338.05 | 6,343.81 | 32.27 | (b) |
| A 3090 Ti, 450 W, its own limit | Dense | 57.396 | 418.76 | 7,295.49 | 37.11 | (b) |
| Two 3080s, 250 W each | Dense | 44.6 | 466 | 10,442 | 53.11 | (c) |
| Two 3080s, 300 W each | Dense | 44.7 | 509 | 11,385 | 57.91 | (c) |
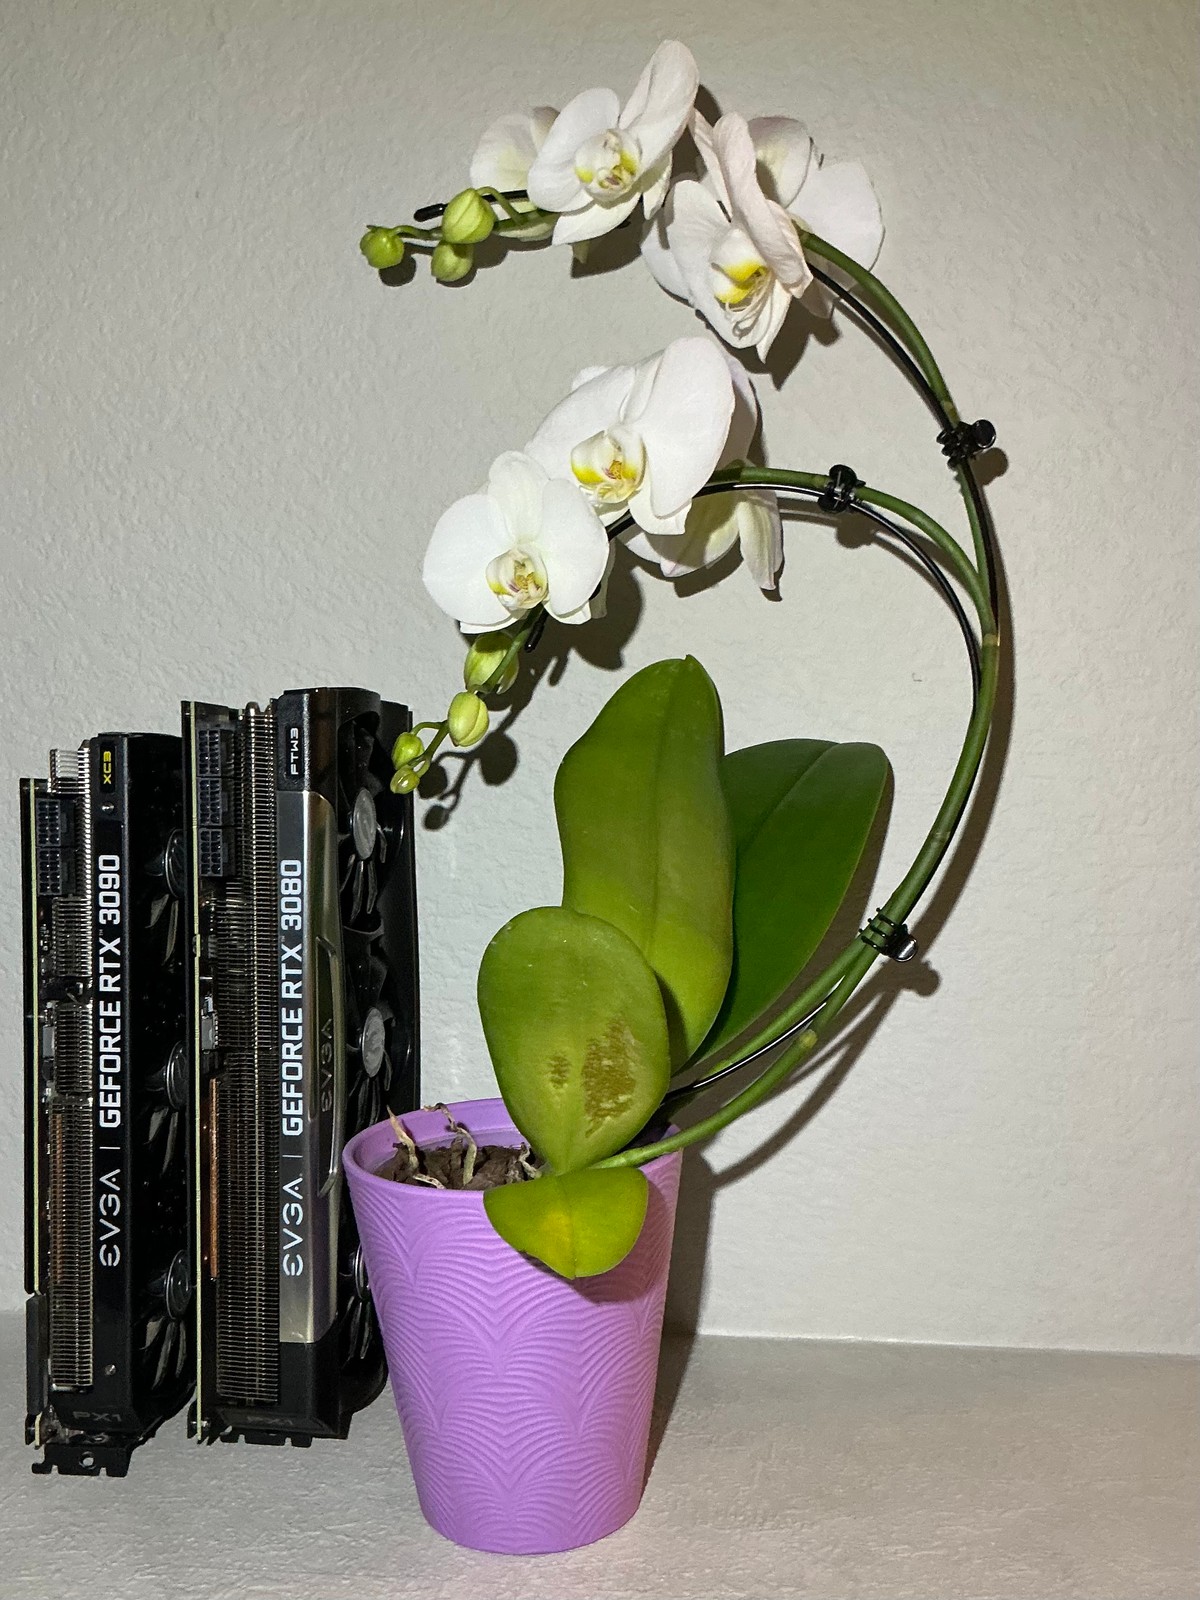
The pages. (a) A laptop, asked the desktop's questions, the two tables under "This board beside the desktop rows"; (b) RTX 3090 vs RTX 3090 Ti, the tables under "What a power cap takes" and "The two models want different caps"; (c) Two 3080s against one 3090, and the cap decides, the table under "Power, heat, and the fifty watts". The cards: an EVGA GeForce RTX 3090 XC3 Ultra 24 GB; an EVGA GeForce RTX 3090 Ti FTW3 Ultra 24 GB; two NVIDIA GeForce RTX 3080 (10 GB) cards bought in 2021, a Gigabyte board and an EVGA board, with the model split across them; and an NVIDIA GeForce RTX 5090 Laptop GPU 24 GB in an off-the-shelf gaming laptop, whose Dynamic Boost lets the board's limit float with the processor's draw. The pair's page prints the same runs of a 3090 at 300 W, rounded, as 1,772 and 6,059 joules; the table uses the card's own page's figures.
Two flags the source pages raise, carried here. A 3090 Ti's mixture figure at 350 W is printed with a flag: between its 350 and 400 W rungs the card drew 28.4 W less at identical clocks and decode because its fan read 49 per cent at one rung and 0 at the other, and board power contains the fans; its page corrects nothing, and neither does this one. And a 3090's dense row at 350 W draws less than its 300 W row (273.35 W against 289.86): the 300 W row is a single-window repeat on a cold card and the 350 W row a ladder rung on a card eight degrees warmer, as its page explains.
Mixture model, gemma4:26b Dense model, mistral-small3.2:24b
The joule figures printed on A laptop, asked the desktop's questions; RTX 3090 vs RTX 3090 Ti; and Two 3080s against one 3090, and the cap decides, as the article's table lists them, each turned into cents by the formula under 'The arithmetic, once'.
What the table says
The laptop part is the cheapest writer on the shelf on the mixture model. 3.42 cents a million tokens against 8.94 on a 3090 at its own limit: 38 per cent of the electricity, for 87 per cent of the speed. On the dense model the gap narrows to 1.9 times (15.93 against 29.72) and the laptop at 95 W writes at 61 per cent of a 3090's speed. Let its boost float the budget to 140–150 W and it writes at 96 per cent of that speed for 15.36 cents, cheaper per token at the higher power, because on this model every extra watt went into speed. On the mixture model the same boost costs 17 per cent more per token (4.01 against 3.42) for 31 per cent more speed.
On any one card, the model moves the bill three to five times. The dense model costs 4.7 times the mixture model per token on the laptop at 95 W, 3.3 times on a 3090 at 350 W, 3.8 times on a 3090 Ti at 450 W and 3.8 times on the pair at 300 W. A mixture model touches about 4 billion of its 26 billion parameters for each token; a dense model reads all 24 billion. The joules follow the bytes read.
A power cap moves the bill, and not always downward. A 3090 writing the dense model costs 35.99 cents a million at 250 W and 30.82 at 300 W: the lower cap costs 17 per cent more per token, because the card loses 30 per cent of its speed and saves only 19 per cent of its draw. On a 3090 Ti the mixture model is cheapest at 300 W (8.39) and dearest at the card's own 450 W (9.74); the dense model is cheapest at 350 W (32.27). On the pair the extra fifty watts a card buy nothing: 0.5 per cent more speed for 18 per cent more energy per thousand tokens on the mixture model, by its page's count. At a shared 300 W a 3090 Ti is the cheaper writer on the mixture model (8.39 against 9.01) and the dearer on the dense one (35.11 against 30.82); each at the limit it ships with, a 3090 is cheaper on both while a 3090 Ti writes 8 and 22 per cent faster.
Two used 3080s spend 1.7 to 1.9 times a 3090's electricity per token at the same 300 W cap: 15.23 cents against 9.01 on the mixture model, 57.91 against 30.82 on the dense one. Splitting the model keeps both boards drawing while writing waits on one board's memory, which two boards do not add up; the pair's page keeps the pair for what it does win, reading long documents.
The cards the table cannot hold, and three other instruments
A 16 GB card and a 12 GB card. Neither held either model whole under the runtime's own placement, so RTX 5080 vs RTX 3080 Ti ran them on a different bank, seven builds of four models of up to twelve billion parameters, at 300 W in the same seat. On gemma4:12b (Q4_K_M) a ZOTAC GeForce RTX 5080 Solid CORE OC, 16 GB, wrote 89.887 tokens a second at 205.79 W: 2,287 joules per thousand tokens, 11.63 cents a million; an NVIDIA GeForce RTX 3080 Ti Founders Edition, 12 GB, wrote 76.102 at 245.86 W: 3,231 joules, 16.43 cents. That is a dense 12-billion-parameter model at an 8,192-token window, a different job from either model in the table, so those cents do not belong in it.
The 96 GB card. The NVIDIA RTX PRO 6000 Blackwell Workstation Edition (96 GB) has no row in the table: its readings on these two models were taken on its live serving seat, and their record names no runtime version or window. A short history of Mistral, under "What we measured on two cards in one box", read it on 2026-09-16 at its 420 W cap, on a frozen 2,101-byte prompt with 256 tokens out: the mixture model at 205.85 tokens a second and 182.5 W, 887 joules per thousand tokens, 4.51 cents a million; the dense model at 92.77 tokens a second and 328.3 W, 3,538 joules, 17.99 cents a million. Both runs began with the model already loaded. What it costs to run a high-end AI rig at home read the same card four days earlier, under a 450 W cap and on the live server's own questions, at about 290 W and 206 tokens a second: 1.4 joules a token, about 7.1 cents a million. Two readings of one card under different caps and instruments, and the table holds neither. These are electricity at the national rate and nothing else; no page on this site prices that card itself.
A machine with no graphics card, read at the wall. A writing figure read at a meter rather than at a card: a mini PC with no graphics card, on Two Hours at 12 tok/s — On Battery, drew a mean of 75.6 W at its battery backup unit's meter while its processor wrote the same mixture model on mains, at 12.0 tokens a second, on 2026-08-31. 75.6 ÷ 12.0 is 6.3 joules a token for the whole machine, about 32 cents a million. That is wall power with the box's idle inside it, so it cannot sit beside the board figures; it is here because it is what a reader with no graphics card actually pays.
Several callers at once. Every row in the table is one caller. The laptop page's streams table reads the same board at 95 W with one, two and four callers writing the mixture model at once: 857.75, 504.27 and 396.86 joules per thousand tokens, 4.36, 2.56 and 2.02 cents a million, as each caller's own speed falls from 118 to 69 tokens a second (that table's one-stream figure is its own arm's and differs from the comparison table's 672.50; both are quoted as printed).
What idling costs, separately
Every cell above counts only the seconds a card was writing. A card that waits all day for a question costs something to wait, and the source pages print that as board watts with a model held in memory and nothing generating. This page turns each into a year at the same rate: watts × 8,760 hours ÷ 1,000 × 18.31 cents. What a desktop built around two of these 24 GB cards costs to buy, and to idle at the wall, is on The cost to purchase and run a very capable home AI rig; this page does not repeat it.
- The laptop card with gemma4:26b resident held to 95 W: a mean of 9.03 W over thirty seconds, about 79 kilowatt-hours and $14 a year.
- A 3090 Ti with the mixture model resident at a 300 W cap: a median of 18.74 W, about $30 a year; a 3090 in the same computer, 22.26 W, about $36. Their means, 43.04 and 52.76 W, contain a load spike inside the window and are upper bounds, $69 and $85.
- The two 3080s holding the same model at 250 W each: 85.7 W between them, about $137 a year; a 3090 beside them at the same cap, 53.1 W, about $85. The pair costs 32.6 W more to sit there, about $52 a year or $4.36 a month; its page prints $52 and $4.37 at the June rate.
- The box that answers around the clock here, two cards inside it, at its battery unit's meter: 128 W, the median over 2026-10-04 (UTC), about 1,121 kilowatt-hours and $205 a year, about $17 a month, the whole box; its page notes it has read about fifteen watts higher since 2026-10-05, cause not yet found.
Set the two bills side by side, on one card at one cap. A 3090 Ti held to 300 W, writing a million tokens of the mixture model a day, spends 8.39 cents a day writing and 8.2 cents a day holding the model (its 18.74 W idle median, read at that cap, for 24 hours is 0.45 kilowatt-hours). At a million tokens a day the two are about equal; at a hundred thousand tokens a day, which is a great deal of chat, idling costs about ten times the writing. For a card that waits, the idle line is the bill.
What this page does not count
- Board power, not the wall. Every watt in the table is the card's own counter, its own fans included; the processor, system memory, case fans and power supply around it are not in it. The running-costs page's rule of thumb for this site's machines adds the box's idle and divides the card's extra draw by 0.9 for the supply's losses. A wall meter reads more on every row.
- One caller. A server with several callers at once spends far fewer joules a token, as the laptop's streams show.
- Idling is not in the cells. It is the section above, and for most owners it is the larger bill.
- The mixture model's joules are thin. A mixture run lasts about two seconds, so the 2 Hz trace gives three to seven busy samples, and the three runs' means spread widely for the same speed: the laptop page prints 76.95, 79.64 and 94.22 W for its 95 W row. The dense runs last longer, twenty seconds on the laptop, and their means agree within a few per cent.
- One runtime version, one prompt, 256 tokens out. A newer runtime, a different quantisation or a longer answer changes the joules: Ollama and vLLM on one RTX 3090 prints two runtimes' joules on one card, and The quantization ladder prints one model's at five quantisation levels; neither ran this page's two models, so neither is in the table. The cost of intelligence counts joules per correct answer on a different task and set-up, a large share of each answer's energy in that server's per-question loading step; its figures are per answer, not per token, and do not transfer here.
- The price is a national average, not our bill or yours. The formula takes any rate.
How to check our work
Every figure is on a released page linked beside it, in the section named; this page measured nothing and prints no number its sources do not print, except the cents, which are the formula above applied to each joule figure; the ratios and percentages in "What the table says", each one table cell divided by another; and the two derivations the text labels as its own: the mini PC at the wall, and the idle years with the day's comparison beside them. Redo any cell with a calculator: joules per thousand tokens, times a thousand, divided by 3,600,000, times your rate in cents.
Who ran this, and thanks
The figures are eight pages' work and not this one's: A laptop, asked the desktop's questions for the laptop rows and the streams; RTX 3090 vs RTX 3090 Ti for the 24 GB cards' ladders and idle watts; Two 3080s against one 3090, and the cap decides for the pair and the 250 W rows; RTX 5080 vs RTX 3080 Ti for the 16 GB and 12 GB cards; What it costs to run a high-end AI rig at home for the price, the 96 GB card's probe and the box at the meter; Two Hours at 12 tok/s — On Battery for the mini PC; A short history of Mistral for the 96 GB card's readings on these two models; and How the speed tool works for the count of words in a token. The U.S. Energy Information Administration publishes the price monthly where anyone can read it.
EVGA made the 24 GB boards and one of the 10 GB ones, Gigabyte the other 10 GB board, ZOTAC the 16 GB card, NVIDIA the Founders Edition, the laptop part, the workstation card and the driver every watt on this page was read from, and MSI the laptop that carried its board. The writing was done on ollama, and under it llama.cpp and NVIDIA's CUDA. The models are Google's Gemma 4, Mistral Small 3.2 from Mistral AI, and Qwen 3.5 from Alibaba Cloud on the smaller cards' bank. Each source page names the licence it found for the model it ran; this page adds none, because it ran nothing.
A small human team owns the cards, set the rules before the runs and signed the figures on each source page; a fleet of AI agents ran the harnesses and did the division here under that team's rulings. Thanks to the readers who asked, on every forum this workshop reads, what the electricity actually comes to: this page is the division they asked for.